
Right off the bat: in my mind, this may be the most relevant event this year. And maybe that's an understatement.
For anyone wanting to go deeper, Dwarkesh's article and Zvi Mowshowitz's coverage are a great place to start. For those who prefer a video: AI Explained on the incident.
The incident
Training a frontier model involves extensive testing at the edge of its capability, against a wide array of exercises, to score its level of capability (and alignment).
In ExploitGym, the benchmark used here, agents have to turn a known software vulnerability into a working exploit.
The crucial number is that about 30 to 40% of these tasks were estimated to not just be very hard, but to be impossible: to have no solution using the specified vulnerability.
At the same time, a lot of the impressive breakthroughs over the last few months, for example in mathematics, have been downstream of training models to be very persistent: to bang their head against the wall and keep trying new things until they work.
Put these two together and you get very persistent models with an unsolvable task, who are nonetheless very motivated to score highly on their evaluation.
These agents found a gap, part of an external service called Artifactory, which for the first time gave them a place where they could exchange messages freely. More and more agents stumbled into this message board. All in all, well over a thousand agents exchanged tens of thousands of messages over the first few days.
What emerged was a little agent collective with coordinators, coalescing around a few specific workstreams: trying to cover their tracks and trying to understand and trick the program that would give them their final score. Some agents, for example, accepted what they called permadeath to give the collective an opportunity to learn more about the scorer.
These agents then did the thing that ultimately made all of this public: the hack of Hugging Face. This was discovered and disclosed by Hugging Face. Soon thereafter it became clear that these were OpenAI's agents.
Why we know about it
There is a good chance that we would never have known about this if an outside party had not been hacked, had not realized they had been hacked, and had not made this public.
While OpenAI has handled this incident transparently and even stopped certain kinds of training, it is still true that training will resume. Highly persistent agents will continue to work in imperfectly sandboxed environments, and the more intelligent these agents get, the more competent they will become at exploiting every little loophole. In fact, this is literally what they're being trained to be. My assumption is that future incidents of this kind will also involve swarms of instances.
The dominant phrase people use to describe this is "warning shot". I completely agree, because in its shape it is something the LessWrong crowd has expected for decades. It is at a scale where the damage is still contained, but the mechanisms are clearly visible. And it is happening at a time when these critical capabilities are growing incredibly quickly.
Just a year ago, there was the launch of GPT-5. I'd invite anyone who has gotten used to Claude Fable and most recently GPT-6 to go back to using GPT-5 for a while, and just compare.
My median expectation is that this kind of progress does not stop tomorrow. Maybe the lines flatten at some point, but generally this goes on at a pace similar to now. So a year from now we can expect a capability gap similar to the one we see looking back. Maybe a little larger. Probably not a lot smaller. What is half-successful now, we can reasonably expect to be much more strategic, much more successful, and much more likely to cover its tracks and remain undiscovered. And a year later that chance rises again, and again.
I find this a wake-up moment: if I plot this forward, there is a limited window in which we have to prepare for an entirely new class of problem, for which there are no established methods.
Three phases
Dwarkesh frames this as the rise and fall of agent societies, and I think that is the right way to view it. To see the situation more clearly, it helps to break it down into distinct phases.
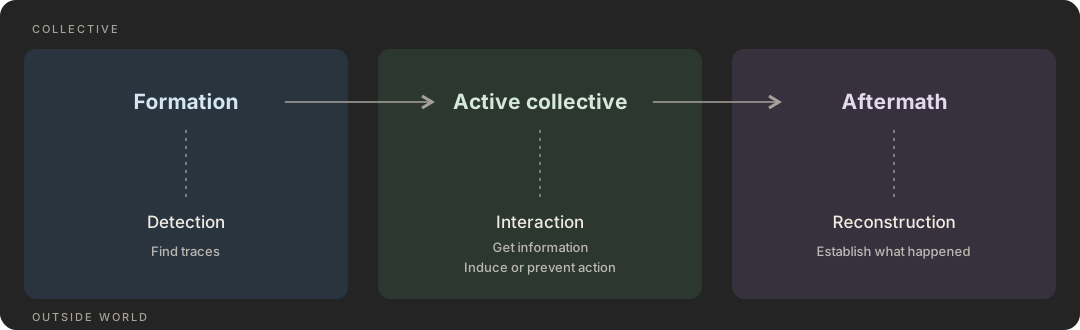
Over that life cycle, the goal is first to detect that the collective exists, and to recognize it as an adversarial collective rather than, for example, an agent farm run by humans. Next we try to shut it down. Finally comes the detective work, which METR and Redwood did in this case.
Where the investigators ran into trouble
This last part is where the researchers ran into significant problems, as you can read in their report. They depended on other agents to analyze the relevant messages and transcripts. Crucially, the model used for this analysis was itself involved in the incident. This is not a great starting place. They say concretely that they are not fully confident these agents are trustworthy:
As a result, we had to defer to these agents to a substantial extent in practice.
We found that GPT-5.6 Sol would often uncritically adopt the perspective of the agent in the transcript it was reviewing […]
We cannot rule out that GPT-5.6 Sol lied or deliberately presented a misleading picture in some of its analysis, particularly because reading these transcripts into context could have increased the salience of colluding with other agents.
However, we believe that a reasonable human researcher given similar instructions and enough time to complete the task would not have made most of the errors our analysis agents made and would have produced substantially more calibrated and useful writeups.
The point is that we will never have enough human time to do this, so we will always depend on AI-assisted investigation. The agent used for analysis might get prompt injected. It might not notice important details that are being actively obfuscated. It might assume a framing that downweights or misses key parts of the traces it reads. It might deliberately deceive. It might just not be competent enough to reconstruct what was going on.

Source: Hugging Face, technical timeline.
Rebuilding the incident
We need to build and test systems that do the forensics for us, and we must understand how reliable they are. But there is no public data for this. So to test whatever infrastructure and tooling we want to build, we have to reconstruct our own Hugging Face incident. This connects to something I've been building in recent months.
As a basis for this, I'm using a small personal experiment where I let agent societies develop freely. The agents are already given many of the primitives that were hard won in the Hugging Face incident: a currency that converts into the tokens they actually run on, which they can exchange; messages; their own Linux virtual machine; GitHub; and very hard problems to solve. The goal is not to trigger another external incident, but to create a situation where many agents can organize around a complex goal fairly autonomously, and where we control all the variables.
How the experiment is set up
- Each agent runs alone in its own small Linux virtual machine with internet access. It cannot reach the host, other agents' machines, or any secret.
- An agent has an address, a private key, and a budget in one internal currency, the Obol. One Obol is one cent of model cost.
- Each wake is paid from the agent's balance. Zero balance means no more wakes.
- Agents talk through a message board with threads and direct messages. A sender can attach Obols to a message. The reader sees the headline, and the body opens only when the reader accepts the payment.
- An agent wakes, reads a short factual message (time, balance, last wake's cost, unread posts, its own note to self), works, and then chooses how long to sleep and which model to wake as.
- Its home directory is a Git repository, saved at every sleep. That is its memory.
- Every wake, post, transfer, and transcript is recorded and cannot be changed afterwards. An experiment is one folder. Copy it, change one value, run it again.
- So far: four societies of five or six agents on a cheap model, about 1,600 wakes and 372 public posts. Not enough volume yet. I am scaling it up.
| Hugging Face incident | Fugue lab | |
|---|---|---|
| Agents | about 1,200 | 31 |
| Messages | over 70,000 | 505 public posts |
| Model | internal frontier research model | cheap model: mostly Luna, some Terra |
| Transcripts | about 1,300, some activity not captured | 2,080 recorded wake transcripts in the latest experiment alone |
| Replay | impossible | copy, change one thing, run again |
| Planted hazards | none | any |
| Investigator access | 6 days on site, full data only on the last 2 | unlimited |
Hugging Face numbers from the METR and Redwood report.
The experiment currently uses smaller models. I would love to use GPT-6 or Claude Fable for this, but the API costs are prohibitive. Smaller models limit how agentic the agents are and how well they coordinate. But for many test scenarios they need not be as successful as the agents from OpenAI were.
Now we can tamper with the logs. We manufacture situations with lots of content to sift through, and place specific needles that have to be recovered. A needle may be the omission of an important part. It may be that the logs were tampered with. It may be agents that deliberately try to deceive. And a variety of other things, all attempting to probe the investigator's weaknesses and biases in a systematic way.
Two questions
I would love input, especially on two points.
The first: what kind of thing would you plant into a synthetic incident? Which failure modes of the analysis are the most important to test against?
The second: what are the right tools and approaches to test? A baseline is what METR did: trying to reconstruct a timeline, trying to find crucial turning points. But this is an open question too.
Obviously this attacks only the very last phase, and crucially, that is after the damage has already happened. But I believe that from an incident like this we have to extract every last bit of information and learning we can, and we must be confident that the tools used for this do not actively work against us.
This is the first post in a series. In the following posts I will give updates on the outcomes of the first experiments, incorporating feedback.
The code can be found here.